


The Core Problem: “Non-Commercial” Doesn’t Mean What You Think
The most common mistake is assuming that working at a university or nonprofit automatically puts you in the clear under an academic or non-commercial license.
Sometimes it does. Often, it doesn’t.
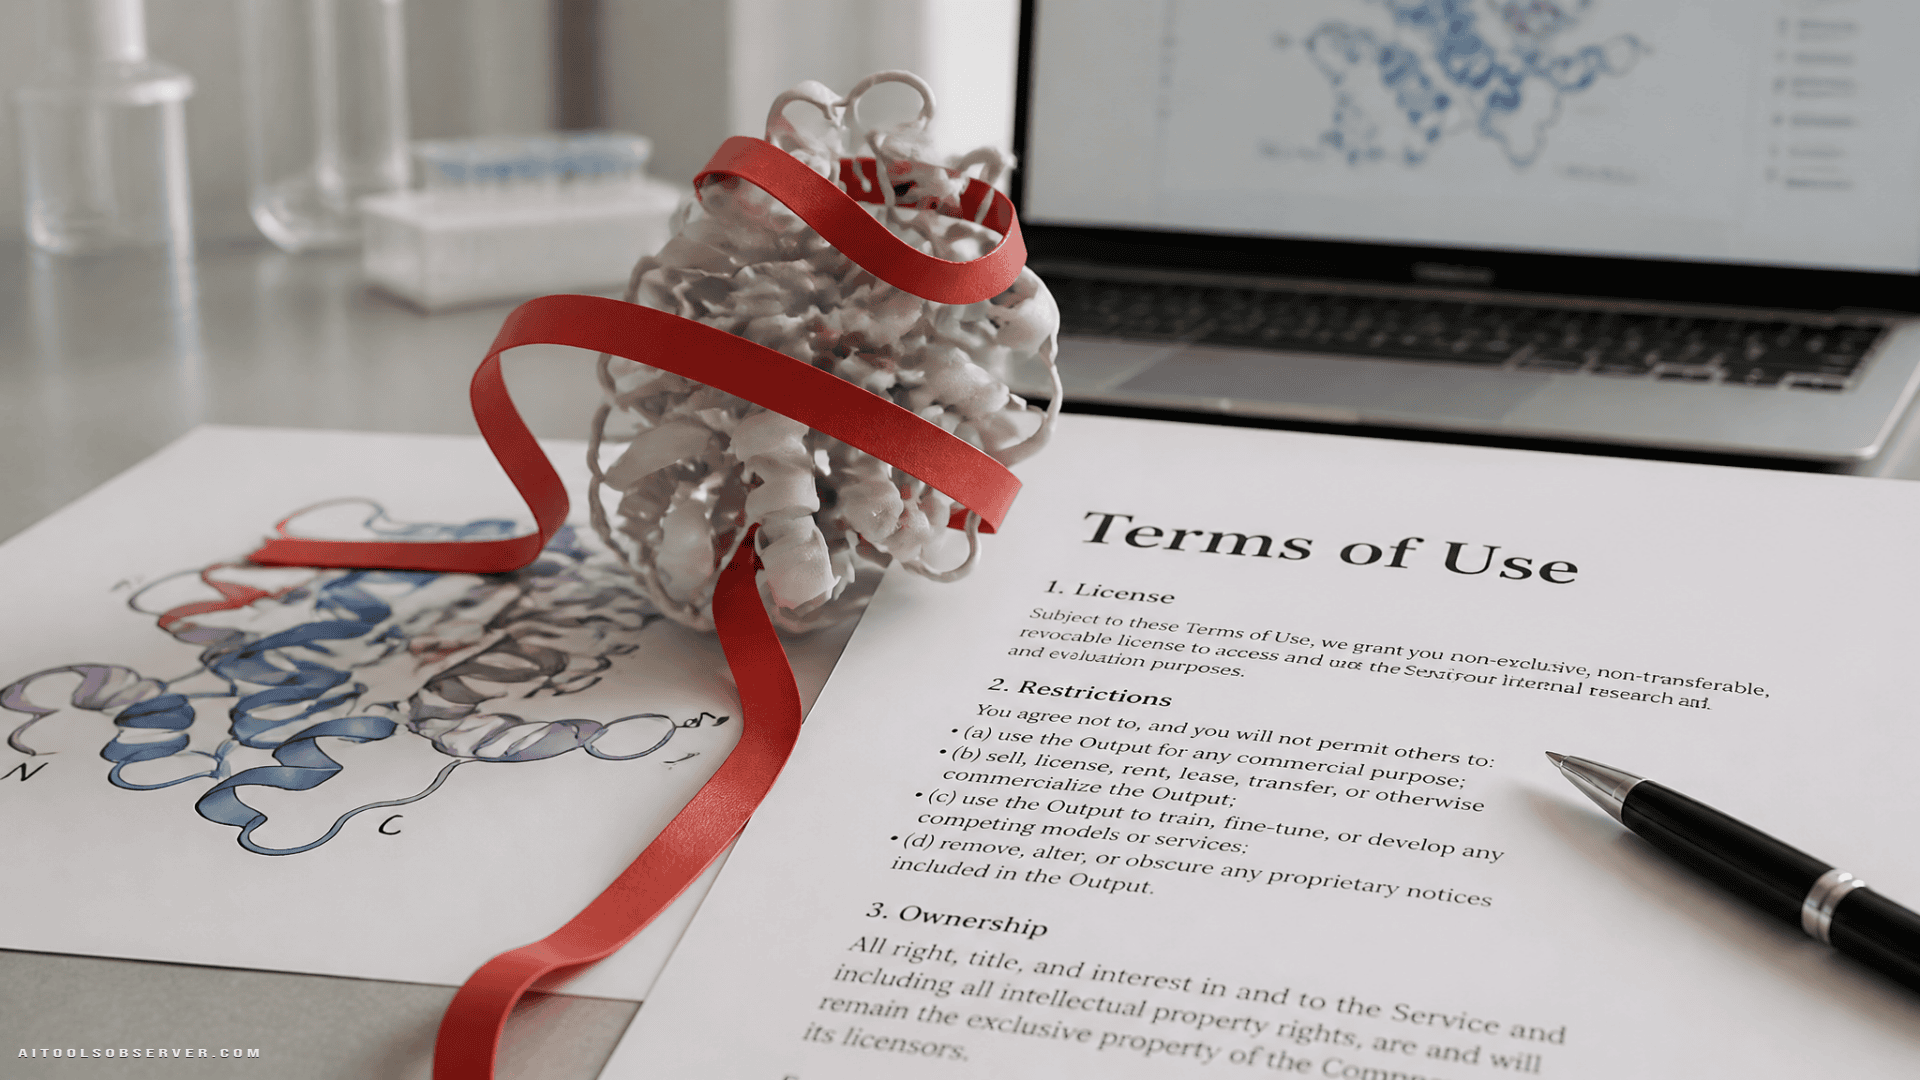
AlphaFold Server — the free, web-based tool operated by Google DeepMind — restricts use to non-commercial purposes and explicitly bars use “in connection with commercial activities,” including research done on behalf of a commercial organization. That’s a meaningful line.
Consider a university lab running a sponsored-research agreement with a biotech partner. The professor uploads a target protein sequence to AlphaFold Server. The lab is academic. The funding is not. If the sponsor receives rights to the resulting structure prediction, that project may no longer qualify as non-commercial use — regardless of the professor’s title or employer.
The Output Terms go further. They prohibit any use of AlphaFold outputs or derivatives that gives a commercial organization rights in those outputs. Publishing results in a journal is fine. Representing that a company owns rights to a structure prediction is not. That distinction directly limits how non-commercial institutions can license their own innovations downstream.
Schrödinger’s Narrow Lane
Schrödinger’s Non-Commercial License follows a similar logic. Qualified Non-Commercial Users can run the software for academic or research purposes, but the license bars any use — directly or indirectly — that supports or is supported by commercial efforts or a commercial enterprise.
There is a carve-out for basic research funded by a commercial entity with no commercial or proprietary interest in the outcome. In practice, that lane is narrow enough that most sponsored research doesn’t fit inside it.
Other AI platforms draw the line differently — not on academic versus commercial status, but on whether you’re using the tool for your own internal purposes versus providing services or results to a third party. That creates real exposure for:
- Contract research organizations
- Sponsored-research projects
- University spinouts receiving results from academic collaborators
Owning Your Inputs Doesn’t Erase Use Restrictions
A common misconception: if you own the data you upload, you own what comes out.
That’s not how these licenses work. Use restrictions apply independently of ownership. Terms like “derivatives,” “output,” and “commercial” are often left undefined or defined loosely enough that reasonable people disagree about where the boundaries are.
The practical implication is straightforward. Before your team uploads a sequence, a compound, or a dataset, you need to know:
- Which platform you’re using
- What license tier applies to your specific use case
- Whether the project has any commercial funding, sponsorship, or downstream commercial intent
Map the use against the license before anything gets uploaded — not after results are already in a report.
Confidentiality: Don’t Assume Platforms Treat Your Data the Same Way
Most researchers assume that what they upload stays private. The reality is more complicated, and it varies significantly by platform.
AlphaFold Server doesn’t include a conventional confidentiality clause. Google’s Privacy Notice permits Google to retain a time-stamped record of the sequences you input and the outputs generated — for an extended period — to monitor compliance and investigate violations. Deleting your Google account or your AlphaFold Server history does not delete that record.
Schrödinger treats uploaded data as confidential and requires confidentiality from both sides. But its hosted-software terms permit Schrödinger to use, compile, store, and process uploaded data to run the software, and to collect anonymized analytics for internal purposes.
Some platforms go further, allowing the use of aggregated, de-identified benchmarking data derived from user inputs. That carve-out deserves scrutiny. A novel compound structure or an unpublished sequence can remain identifiable inside an aggregated dataset simply because so few labs work on it. For high-value programs, the safer approach is to avoid uploading sensitive data altogether until you’ve had a legal review.
The Patent Filing Problem Nobody Talks About
This is the issue that gets the least attention and carries some of the highest stakes.
Under Schrödinger’s Non-Commercial License, results, inventions, or discoveries generated using the software must be publicly disclosed — not kept confidential or proprietary — unless the licensee pays in advance to upgrade to a commercial license at Schrödinger’s then-current pricing.
The same terms impose a punitive patent-filing fee if the licensee files a patent application containing a claim based on platform output without first subscribing to a commercial license.
That’s a direct hit to tech transfer operations. If a researcher used a non-commercial AI tool during the discovery process and no one flagged it before the patent application was filed, the institution may face unexpected fees or disclosure obligations that complicate or compromise the filing.
Tech transfer offices should be asking one question before every patent application: what AI tools were used in this research, and what do their licenses say about patent filings?
What to Actually Do About This
None of this means these tools are too risky to use. They’re genuinely useful, and avoiding them entirely would put labs at a competitive disadvantage.
It means you need a process.
For academic and research institutions:
- Audit which AI tools researchers are actively using
- Identify which projects have commercial sponsors or downstream commercial intent
- Flag those projects for license review before any outputs are used in filings, reports, or agreements
- Build AI tool disclosure into tech transfer intake processes
For biotech and pharma teams:
- Don’t assume your internal R&D team is covered under an academic license just because a collaborating university is
- Pull every referenced agreement — not just the Terms of Use, but also the Privacy Notice and any supplemental terms
- Evaluate confidentiality terms before uploading proprietary compound data or unpublished sequences
For executives and general counsel:
- Treat AI tool licensing as a category of IP risk, not just an IT procurement issue
- Build license review into project onboarding, not just contract review at the end
For teams already reworking review processes around compliance and life sciences paperwork, this is part of the same operational discipline.
The Takeaway
The fine print in AI drug discovery tools isn’t designed to trap researchers. But it is designed to protect the platforms — and it can create serious commercialization risk for labs and companies that don’t read it carefully.
The gap between “we used this tool in our research” and “we have clean commercial rights to what came out of it” is wider than most teams expect. Closing that gap is a legal and operational task, not just a compliance checkbox.
The teams that build these reviews into their workflows now will avoid the harder conversation later — the one that happens after a patent has been filed, a spinout has been formed, or a licensing deal is already on the table.
That matters across AI-enabled medical research, especially where discovery work may later move toward commercialization.


Comments (0) No comments yet
Want to join this discussion? Login or Register.
No comments yet. Be the first to share your thoughts!