


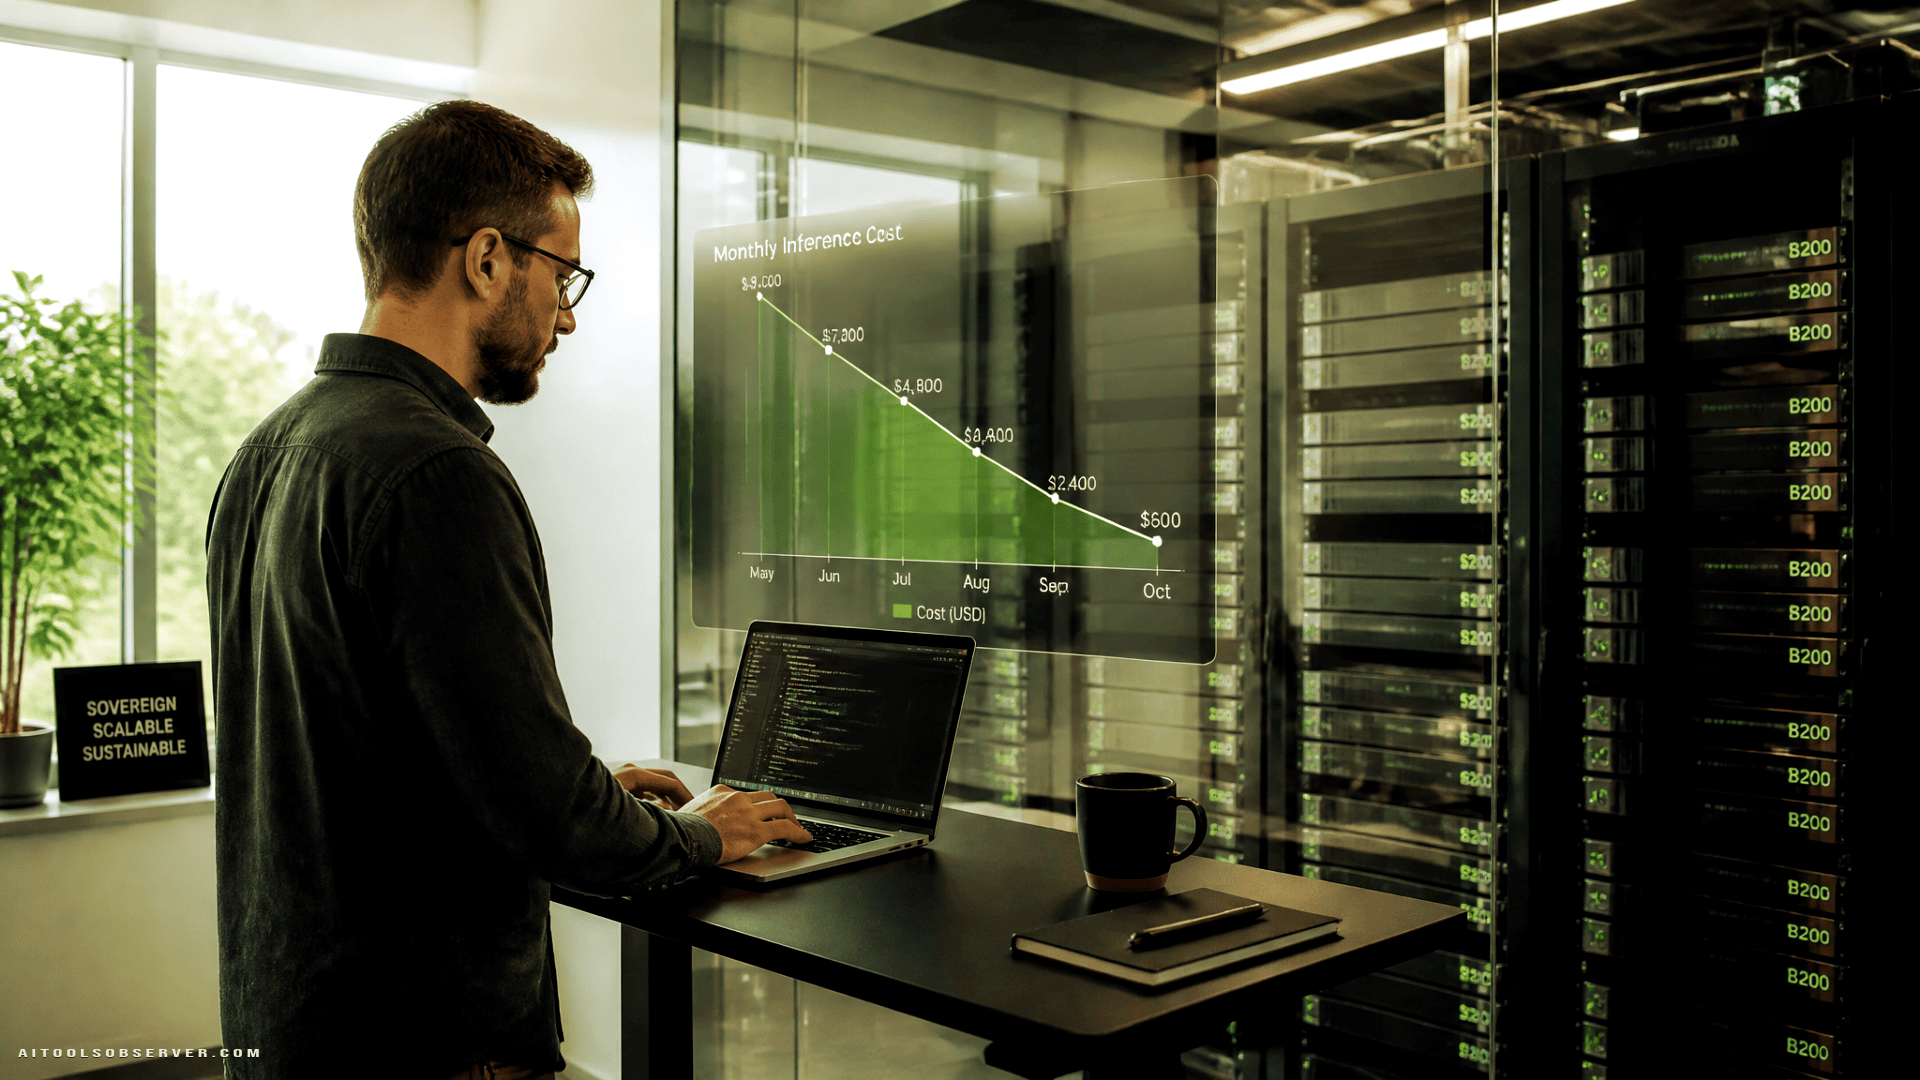
The problem: useful tools, ugly economics
Before shifting its setup, Revolut had already tested mainstream coding assistants, including Gemini and Claude Code. The issue wasn’t whether engineers could use them. The issue was whether the company could scale that use without creating a monthly surprise nobody wanted to defend.
That led to strict token budgets. Which is logical on paper and annoying in practice.
When tokens are rationed, people use AI sparingly. They save it for “important” tasks, avoid exploratory work, and think twice before asking the model to do the messy, repetitive stuff that actually eats time every day.
Why self-hosting changed the math
The big shift came from self-hosting GLM rather than relying entirely on paid API access for coding workloads.
Based on the available context, Revolut found the economics dramatically better. The key benefit wasn’t just lower per-token cost. It was behavioral: once tokens became cheap enough, engineers stopped treating every prompt like a budget meeting.
That matters more than it sounds.
Cheap inference changes how teams work:
- More debugging help
- More documentation support
- More ticket summarization
- More parallel experimentation
- Less hand-wringing over whether a prompt is “worth it”
In other words, lower cost didn’t just reduce spend. It expanded the set of tasks AI could handle without friction.
The real productivity gain wasn’t pure code generation
This is the part many teams miss.
Revolut reportedly saw improvements in coding speed, but the biggest gains didn’t come from having the model write more code faster. They came from offloading adjacent work: debugging, Jira tasks, and Confluence-heavy knowledge retrieval.
That’s a more useful lens for enterprise buyers.
AI coding ROI often gets framed as “How many lines of code did the model write?” A better question is: “What work stopped interrupting the engineer?”
If AI handles the annoying context-switch tax, the value compounds:
- Fewer broken concentration cycles
- Less time digging through internal docs
- Faster issue triage
- More willingness to use AI throughout the workflow, not just at the finish line
Why the hardware story matters
Self-hosting a large open-weight model is not a hobby project with a spare workstation and optimism.
The description suggests Revolut first used GLM-5.1, then moved to GLM-5.3, serving it with 56 Nvidia B200 GPUs. That’s a serious deployment, and it tells you two things immediately.
First, the company wasn’t chasing “cheap AI” in the simplistic sense. It was optimizing total economics at enterprise scale.
Second, cost savings from self-hosting only work if you can actually run the model well. A low token price means less if the user experience feels like sending prompts by carrier pigeon.
The smarter lesson: optimization beat brute force
One of the more practical takeaways here is that more GPUs alone were not presented as the main source of performance gains.
Instead, the improvements came from systems tuning:
- NVFP4 quantization
- Disaggregated prefill and decode
- Hyperparameter tuning
- Context-length tuning
That’s a useful reminder for infrastructure teams. Performance comes from architecture decisions, not just hardware invoices.
There’s a tendency in enterprise AI to solve every serving problem with bigger clusters. Revolut’s setup suggests the better approach is usually: tune first, then scale what actually helps.
Long context sounds cool. Useful context is better.
The article’s sharpest lesson may be the least glamorous one: a giant context window is not automatically a good product decision.
Yes, the model could support extremely long context. But the practical sweet spot appears to have been much lower, around 256,000 tokens rather than chasing the maximum headline number.
That’s a helpful correction for teams dazzled by spec-sheet theater.
A one-million-token window looks great in demos and vendor decks. In actual workflows, what matters is:
- whether the model stays responsive
- whether the extra context improves outputs
- whether users are willing to wait for it
- whether the infrastructure bill remains sane
More context is only better when it creates better work, not bigger bragging rights.
The UX benchmark was simple: don’t make engineers wait
Revolut’s internal target appears refreshingly grounded.
Sub-3-second time to first token was treated as the sweet spot. Once latency drifts too far upward, user complaints arrive fast. That tracks with broader product reality: engineers will tolerate a lot from AI, but sluggishness is not one of those things.
Generation speed also mattered less than many teams assume. Around 200 tokens per second seems to have been acceptable for interactive use, with much higher throughput available during off-peak hours.
That hints at an important enterprise truth: perceived responsiveness matters more than raw benchmark flexing.
People don’t sit and admire token streams all day. They kick off tasks, switch tabs, review outputs, and run multiple things in parallel. Your serving stack should match that behavior.
GLM didn’t replace everything
This wasn’t a winner-takes-all migration.
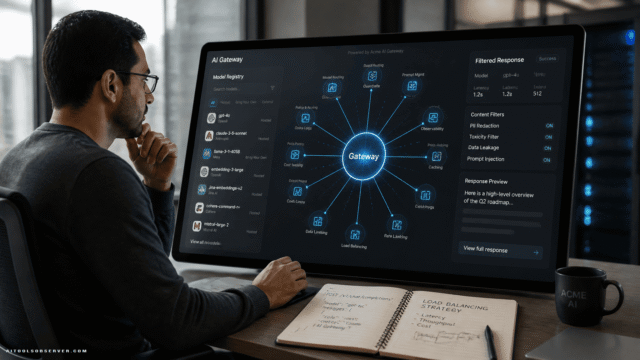
GLM was used for text-heavy coding workflows, but not for every use case. Because it’s text-only, it wasn’t ideal for UI-related work or vision tasks. So Revolut used model routing to send those requests to other models such as Gemini or GPT-family options, while keeping code generation on GLM.
That’s probably the most realistic part of the whole setup.
For most enterprise teams, the end state is not “one model to rule them all.” It’s:
- one model for cheap, frequent core tasks
- other models for specialized edge cases
- a routing layer that hides the complexity from users
This is usually how mature AI stacks evolve: not toward purity, but toward sensible division of labor.
What enterprise teams can learn from this
You don’t need 56 B200 GPUs to apply the core lesson.
What matters is the operating model behind the deployment:
- Identify where token cost is suppressing usage.
- Separate core high-volume workloads from premium edge cases.
- Self-host where economics and control improve materially.
- Route specialized requests to external frontier models when needed.
- Optimize latency and context around real user behavior, not marketing specs.
The broad takeaway is simple: AI becomes more useful when people stop fearing the meter.
If every prompt feels expensive, adoption stays cautious. If costs are predictable and performance is good enough, usage spreads into the boring workflows where real ROI usually lives.
The tradeoffs are real
This case is not an argument that every company should immediately self-host a giant model.
There are obvious constraints:
- significant infrastructure requirements
- serving and optimization complexity
- model-specific limitations
- governance and security review
- the need for internal platform talent
There’s also a strategic tradeoff. Self-hosting can flatten costs and reduce bill shock, but it shifts responsibility onto your team. You are no longer just buying intelligence. You are operating it.
For some companies, that’s a feature. For others, it’s a full-time headache wearing a cost-saving hat.
A practical takeaway for buyers
If you’re evaluating AI coding tools, don’t just compare model quality. Compare usage economics under realistic team behavior.
The better question is not “Which model writes the best code in a benchmark?” It’s “Which setup lets our team use AI freely across coding, debugging, documentation, and internal workflows without turning every month-end review into damage control?”
That’s the real case study here.
Revolut didn’t just lower token costs. It appears to have built a setup where engineers could stop hoarding prompts and start using AI where work actually gets stuck. For enterprise teams, that’s often the difference between an AI pilot and an AI habit.


Comments (0) No comments yet
Want to join this discussion? Login or Register.
No comments yet. Be the first to share your thoughts!