
The Core Problem: Stale KV Cache Pages Crossing Request Boundaries
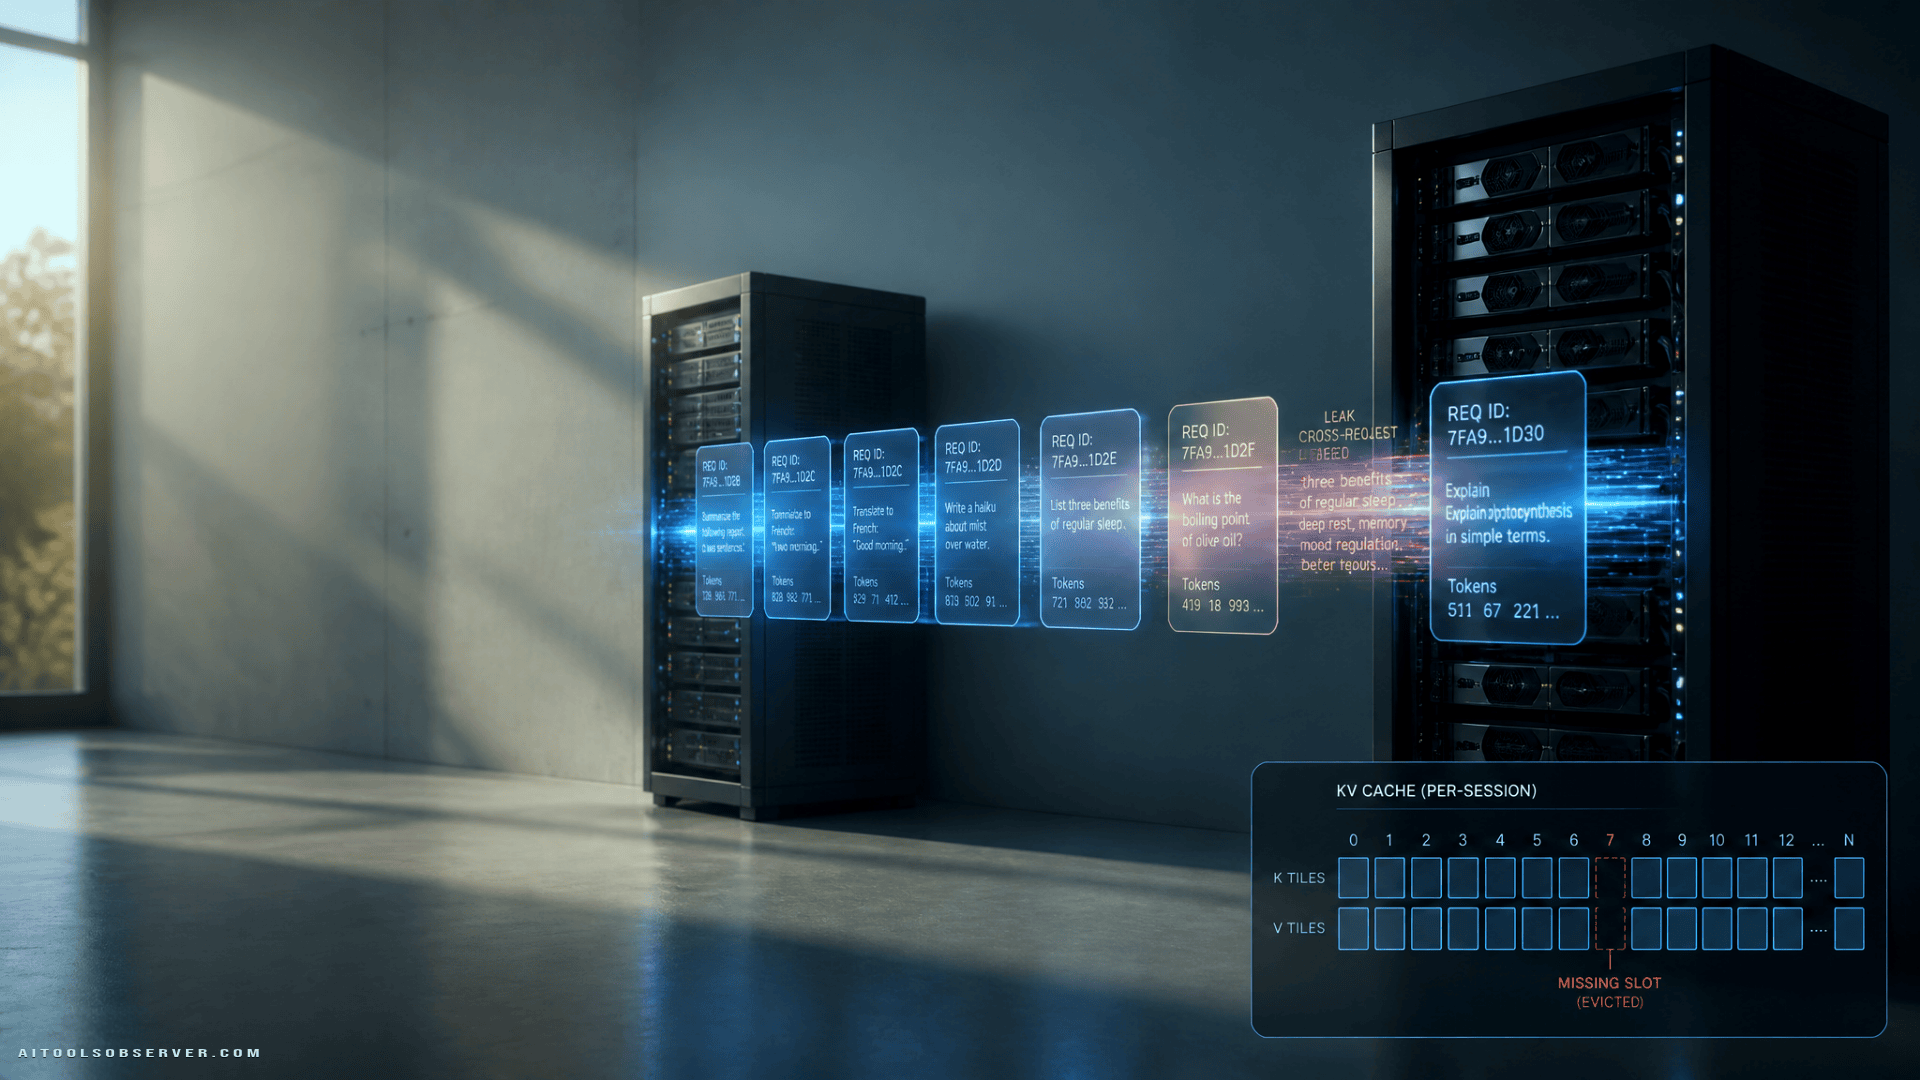
Large language models use a structure called a KV cache (key-value cache) to store intermediate computations while processing a prompt. In a shared inference environment, that cache lives in a pool of GPU memory pages. Pages get assigned to a request when it arrives and released when it finishes—but they are not wiped clean between uses.
That’s normal. It’s also how high-performance inference engines stay fast. The engine is responsible for tracking which pages belong to which request. When that tracking breaks down, one user’s data can end up in another user’s response.
That’s exactly what happened here.
Issue 1: A Configuration Mismatch
Cloudflare deployed GLM-5.3 with a context window of 1,048,576 tokens. But the KV cache pool on the prefill GPUs only had room for 681,280 tokens. That’s a meaningful gap.
Cloudflare was aware of the mismatch before launch. During testing, long-context requests returned successful HTTP responses with no visible errors, so the team assumed the engine was handling the overflow gracefully. It wasn’t.
The gap in testing: response codes and throughput were validated, but the actual content of responses at long contexts was not checked for coherence or cross-contamination.
Issue 2: A Bug in SGLang’s Disaggregated Mode
Cloudflare runs GLM-5.3 using SGLang in a disaggregated prefill/decode configuration. Prefill GPUs process the prompt and build the KV cache. That cache is then transferred over RDMA to decode GPUs, which generate the response. It’s a performance-oriented architecture that separates the two most expensive phases of inference.
When a prompt arrived that was longer than the KV cache pool could hold, SGLang’s scheduler correctly identified it as too large and marked it as rejected. But the rejection path had a flaw in disaggregated mode.
Here’s what actually happened step by step:
- The router told the decode node to reserve 8 KV pages for the request.
- The prefill admission queue checked whether the request was “finished”—not whether it was rejected. A rejected request still appeared live, so it was admitted.
- Rejection had already swapped the real prompt for a one-token placeholder. Prefill ran a trivial forward pass on that single token.
- Prefill transferred one page of KV data to decode and signaled that the transfer was complete.
- Decode’s admission queue had the same flawed check and accepted the handoff.
- Decode started generating and read all 8 reserved pages. Only one page had been written by this request. The other seven still held data from earlier requests—other users’ prompts and partial generations.
- The client received an HTTP 200 response containing content from other users’ sessions.
In total, 155 responses were affected—all to prompts longer than 681,280 tokens. Cloudflare found no evidence of deliberate exploitation. The affected requests appear consistent with ordinary long-context use.
How Cloudflare Fixed It
The model was taken offline within 40 minutes of the incident being declared on September 9. Two fixes were deployed before service was restored the same day.
Fix 1: Correct the configuration. The KV pool was expanded to approximately 2.04 million tokens—roughly twice the context window. Any valid prompt now fits the pool, so the rejection path is never triggered for a legitimate request.
Fix 2: Patch the engine. Relying on pool size alone is fragile. Changes to quantization, tensor parallelism, or CUDA graph sizes can shift the pool size in ways that are easy to miss. Cloudflare patched SGLang so that any request carrying a pending rejection is retired at the disaggregation admission queue—before bootstrap, memory allocation, or KV transfer happens. The decode node also now verifies that the number of tokens transferred matches the number it reserved.
Both fixes were validated against the researcher’s reproduction script and Cloudflare’s own canary-marker tests before the model was restored.
The Broader Class of Bugs This Belongs To
This incident isn’t an isolated quirk. It belongs to a broader category of KV cache memory-safety bugs that Cloudflare has been working to address with the SGLang team for several months.
The common thread: a memory page is freed, reused, or read while something else still has a claim on it. Two patterns keep appearing:
- Page lifetime within a single node. Multiple tasks—token generation, host memory offload, KV transfer, abort paths—can hold the same page simultaneously. If one frees it while another is still using it, a new request can be assigned that page mid-operation.
- Race conditions across nodes. When a request is aborted while prefill is still writing KV data to decode over RDMA, those in-flight writes can’t be recalled. If decode frees the pages immediately, a new request can receive them—and the late writes land in the wrong request’s cache.
The GLM-5.3 bug was different in mechanism (a rejected request going through the handoff every time, not by timing accident) but identical in consequence: decode reading pages it never wrote.
In shared systems, that kind of failure can become a data leak problem very quickly.
What SGLang Has Released
Cloudflare worked with the SGLang maintainers at RadixArk to upstream fixes. The following changes are now available, with most included in SGLang v0.5.22:
Directly addressing this incident:
#36988(v0.5.20) — Retires aborted prefill requests before their result reaches decode.#38935(v0.5.21) — Rejects over-length requests at admission, before any bootstrap or KV transfer.
Addressing related race conditions:
- Deferred KV release turned on by default, covering every failure type, not just aborts.
- Client disconnects no longer abort a request mid-transfer.
- Failed Mooncake sends no longer report their writes as drained.
- Abort messages tagged per request so a reused ID can’t consume a stale confirmation.
Observability improvements:
--disaggregation-enable-kv-checksumflag: decode verifies a checksum of transferred KV before generating.- Metrics for deferred release duration and outcome.
- Fixes to SGLang’s KV canary, which detects and logs potential corruption.
Still in progress:
- Zeroing KV pages on release.
- Extending KV checksum validation beyond the prefill-to-decode handoff to every decode step.
Cloudflare strongly recommends all operators running disaggregated SGLang update to v0.5.22 or later.
What This Means If You Run LLM Inference
A few practical takeaways worth internalizing:
Validate output content, not just response codes. Cloudflare’s pre-launch testing confirmed successful HTTP responses at long contexts. It didn’t confirm that those responses were coherent or free of cross-contamination. Response codes tell you the engine didn’t crash. They don’t tell you what the engine actually returned.
KV pool size and context length are independent settings. In SGLang, the pool is sized at startup from available GPU memory after model weights load. The context length is a separate config value. Nothing automatically enforces that they agree. Check them explicitly before deploying.
Disaggregated inference adds new failure surfaces. Splitting prefill and decode across separate GPU pools improves throughput, but it also means ownership of KV pages spans a network boundary. Abort paths, error handling, and memory lifecycle all need to account for that distributed state.
Tenant isolation in shared inference is a hard problem. Not zeroing pages between requests is a deliberate performance tradeoff, not a mistake. But it means the correctness of your memory tracking has direct security implications. Any bug in that tracking is a potential data leak.
The GLM-5.3 incident was contained quickly, affected a small number of requests, and appears to have been discovered through responsible disclosure rather than active exploitation. The response—transparent post-mortem, coordinated upstream fixes, hardened deployment checks—is a reasonable model for how these incidents should be handled.
The underlying class of bugs, though, is still being worked through. If you’re operating LLM inference infrastructure at scale, the SGLang changelog from v0.5.20 through v0.5.22 is worth reading carefully.


Comments (0) No comments yet
Want to join this discussion? Login or Register.
No comments yet. Be the first to share your thoughts!