

The Problem Agentic AI Created
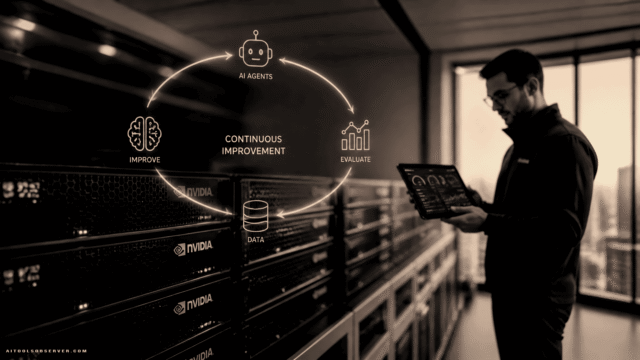
AI agents don’t just run one big matrix multiply and call it done. They loop. They call tools, execute code, wait for results, reason about what happened, and loop again. Every one of those steps touches the CPU — and a slow CPU means an expensive GPU sitting idle.
That’s the bottleneck Vera is designed to eliminate. High single-threaded performance, low latency, and fast memory bandwidth aren’t nice-to-haves here. They’re the whole point.
Why Chiplets Lost This Round
The chiplet trend made sense when the goal was cramming more cores into a die. More cores, more throughput, done. But chiplets carry a hidden cost: when data has to cross the boundary between chiplets, you pay a latency tax on every trip.
For agentic workloads — where cores constantly share context and collaborate on reasoning loops — that tax compounds fast.
NVIDIA’s answer with Vera is a monolithic die. Every core on a single continuous piece of silicon, no I/O boundaries to cross. The result, based on the available context, is 3.4 terabytes per second of bisection bandwidth — roughly 3x higher than leading x86 chips. Cores can share context three times faster. For agents juggling multi-step tasks, that’s not a marginal gain.
NVIDIA is clear that this isn’t a religion. If a future market demands chiplets, they’ll use chiplets. But for this specific problem, monolithic won.
Single-Threaded Performance Is Back
The broader industry spent years trading single-threaded speed for core density. Vera is a deliberate reversal of that trade.
Compared to its predecessor Grace, Vera delivers around 1.5x faster performance overall. Against leading x86 processors on agentic workloads specifically — think Python scripting, code compilation, sequential reasoning tasks — the gap appears to reach 2x.
That gap exists because x86 chips are designed to serve many masters: consumer laptops, enterprise servers, gaming rigs. NVIDIA entered the standalone CPU market with no legacy segments to protect, which gave them the unusual luxury of designing Vera purely for the data center and agentic AI use case.
Spatial Multithreading Without the Tax
One of the more interesting architectural choices in Vera is what NVIDIA calls Spatial Multithreading. Rather than traditional simultaneous multithreading — where threads compete for the same resources — Vera provisions dedicated worker threads and I/O threads separately.
The practical effect: under heavy load, background I/O operations don’t cannibalize the cycles your agent actually needs. Independent testing cited in the available context suggests this approach delivers roughly a 20% performance uplift rather than the overhead penalty some expected.
It’s a small architectural detail with a meaningful operational consequence.
The Standalone CPU Rack Is Now a Real Thing
Perhaps the most structurally interesting shift here isn’t the chip itself — it’s how NVIDIA is positioning it.
Vera started life as a host node inside the Vera-Rubin combined CPU-GPU stack. The new direction is standalone CPU racks: pure rows of Vera processors handling agent tool calls and reinforcement learning tasks, completely separate from GPU infrastructure.
Some sandbox providers are reportedly hosting hundreds of thousands of sandboxes for a single customer. At that scale, the CPU-to-GPU ratio in AI environments starts to look very different from the traditional 1-to-4 or 1-to-8 configurations. NVIDIA won’t put a number on where that ratio lands — which is itself a signal that the number is moving fast enough to be commercially sensitive.
What This Means for AI Infrastructure Decisions
If you’re evaluating AI infrastructure today, a few things are worth keeping in mind:
- GPU utilization depends on CPU speed. Slow CPUs don’t just waste CPU cycles — they waste GPU cycles. The two are more tightly coupled in agentic workloads than in traditional inference.
- Disaggregation is accelerating. Pre-fill and decode already run on separate hardware in many inference setups. Standalone CPU racks for agent orchestration are the next logical step.
- Monolithic vs. chiplet is a workload question, not a universal answer. Vera’s monolithic design wins on latency and bisection bandwidth for agentic loops. That advantage may not apply equally to every workload type.
The Useful Takeaway
The CPU wasn’t supposed to matter this much again. Agentic AI changed that by making sequential, low-latency reasoning loops the critical path — and the critical path always determines where bottlenecks live.
Vera is NVIDIA’s bet that the CPU is now a first-class citizen in AI infrastructure, not a support act. Whether or not you’re evaluating NVIDIA hardware specifically, the underlying shift is real: if you’re building or buying for agentic workloads, the CPU spec sheet deserves the same scrutiny you’ve been giving the GPU.


Comments (0) No comments yet
Want to join this discussion? Login or Register.
No comments yet. Be the first to share your thoughts!